Newsletter September 2026
We're back! In fact we are soooo back with a special announcement about RM Compare | NOW, our new on-demand mobile Comparative Judgement experience.


We're back! In fact we are soooo back with a special announcement about RM Compare | NOW, our new on-demand mobile Comparative Judgement experience.

You are invited to try out the worlds first mobile, on-demand Adaptive Comparative Judgement experience. For those following closely this has been quite a journey and long term ambition. There is still more to learn and more to do, but reaching this release is a significant step.

Shared Standards connects assessment evidence across RM Compare. Studio creates comparative ranks, Hub securely governs mark-derived and ACJ evidence, and Live applies approved rulers to new work. Together, they support consistent standardisation, moderation and on-demand comparison - helping organisations make professional judgement transparent, reusable and reliable.
Moving beyond the transactional illusion of AI-era education. A student can now sit alone, prompt a machine and produce a polished essay, working code or a plausible solution to a complex problem in minutes. For education, that is more than an administrative headache. It challenges a familiar assumption: that a finished piece of work, submitted out of sight, is reliable evidence of what a student knows, understands or can do.
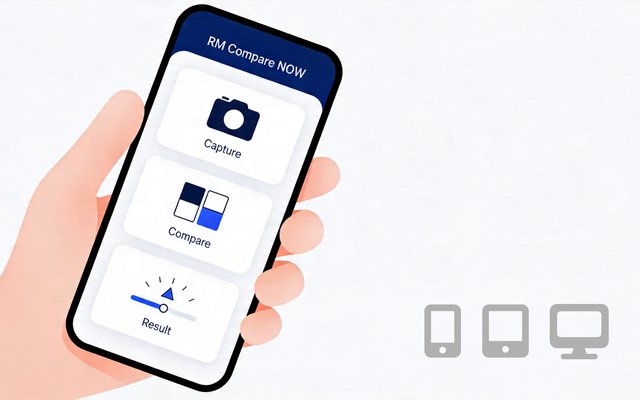
In the last post, we introduced Assessment as Learning and the idea of Guild Knowledge - the tacit, experience‑based ability to recognise quality that experts build over time. RM Compare | ⏱️NOW gives people a short, structured way to test and develop that ability by estimating quality, making comparisons, and seeing how accurate their judgement is.
⏱️RM Compare | NOW isn't just a convenient demo or a quick assessment tool. It's a practical example of Assessment as Learning - a pedagogical approach that helps people develop what's called Guild Knowledge.
For a long time, the debate about AI in assessment focused on capability. Could AI produce judgements that were reliable enough to take seriously? Could it handle open-ended responses, complex performances, or evidence of learning that did not fit neatly into a mark scheme?
RM Compare launches a new era of on-demand Comparative Judgement. There has never been a more uncertain time in education. There has never been a more exciting time to be in education.
RM Assessment, who provides RM Compare, is moving to a new legal entity from 1 June 2026.
Every few years, a body of evidence emerges from an unexpected direction that turns out to be exactly what education needed to hear. We think this might be one of those moments.
When important decisions, results or reputations depend on a piece of software, “quality” stops being a nice‑to‑have. It becomes the question of whether that system will be there when people need it, and whether it can adapt as your needs change.
AI assessment has a dignity problem. Not a technology problem, or even just a fairness problem, but a problem with how it treats people at precisely the moments they are most exposed and most human.
Assessment systems often talk about standards, but too often those standards remain abstract. Teachers, examiners and assessors are expected to align to a wider benchmark, yet in day-to-day practice they usually see only the work directly in front of them: their own class, their own cohort, their own centre. That gap matters.