NEW! ⚡NOW LbE Reporting
The new ⚡|NOW reporting allows a user to view work from the standard that is of a similar standard to their own, as well as work that is of a quality that is a little higher and a little lower.

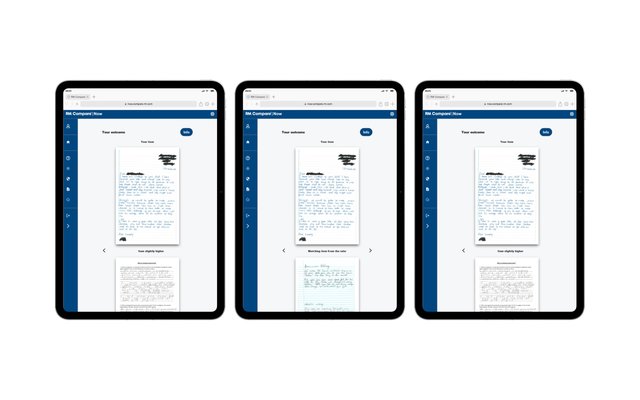
The new ⚡|NOW reporting allows a user to view work from the standard that is of a similar standard to their own, as well as work that is of a quality that is a little higher and a little lower.

Despite being only a few weeks since our last Newsletter, we have plenty to share in this update, the highlight being the extension of RM Compare | ⚡NOW onto non-mobile devices.
When you build a mobile experience for comparative judgement, the temptation is to start with the desktop application and ask: how can we fit everything onto a smaller screen? With RM Compare |⚡NOW, we asked a different question: what does someone need to make a useful comparison, right now?
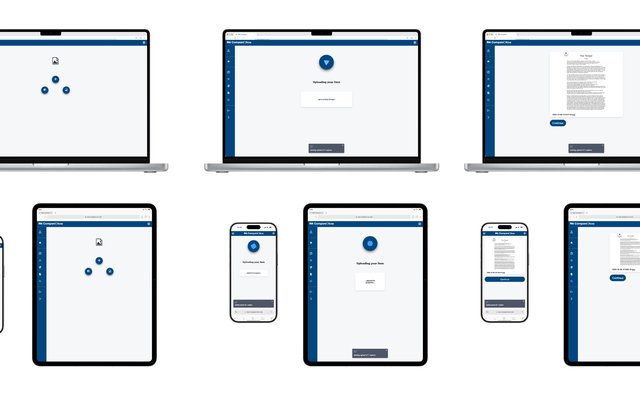
Hot on the heels of the 'mobile first' release of RM Compare | ⚡NOW. we are pleased to make it accessible on any* device.
For a long time, the debate about AI in assessment focused on capability. Could AI produce judgements that were reliable enough to take seriously? Could it handle open-ended responses, complex performances, or evidence of learning that did not fit neatly into a mark scheme?
RM Compare launches a new era of on-demand Comparative Judgement. There has never been a more uncertain time in education. There has never been a more exciting time to be in education.
RM Assessment, who provides RM Compare, is moving to a new legal entity from 1 June 2026.
Every few years, a body of evidence emerges from an unexpected direction that turns out to be exactly what education needed to hear. We think this might be one of those moments.
When important decisions, results or reputations depend on a piece of software, “quality” stops being a nice‑to‑have. It becomes the question of whether that system will be there when people need it, and whether it can adapt as your needs change.
AI assessment has a dignity problem. Not a technology problem, or even just a fairness problem, but a problem with how it treats people at precisely the moments they are most exposed and most human.
Assessment systems often talk about standards, but too often those standards remain abstract. Teachers, examiners and assessors are expected to align to a wider benchmark, yet in day-to-day practice they usually see only the work directly in front of them: their own class, their own cohort, their own centre. That gap matters.
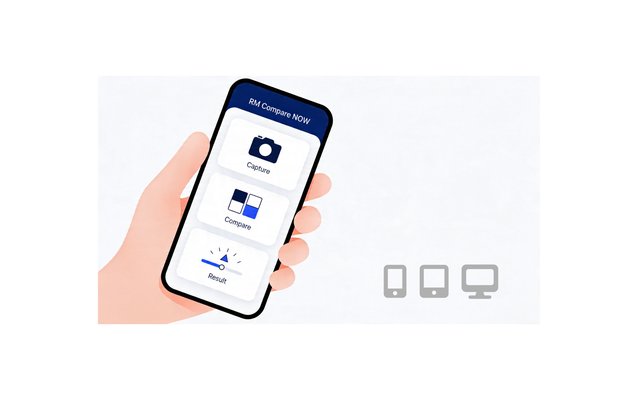
We’re pleased to announce that RM Compare | ⚡NOW is now in ALPHA. It is a lightweight RM Compare experience designed for quick judgements, allowing users to capture or upload an item, compare it to a ready-made standard, and review a score in just a few steps.
If the first post in this series traced the industrial birth of marking, the second described the temptation to use AI as a faster horse, and the third argued for rediscovering human judgement, this final post asks the practical question: what would assessment look like if it were designed for the world now emerging rather than the one that produced marks and grades?