NEW! ⚡NOW LbE Reporting
The new ⚡|NOW reporting allows a user to view work from the standard that is of a similar standard to their own, as well as work that is of a quality that is a little higher and a little lower.

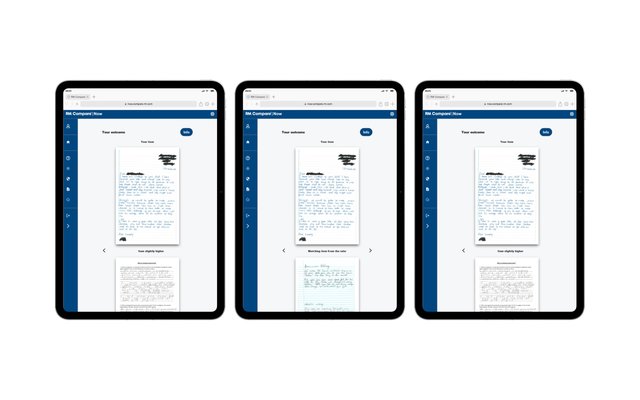
The new ⚡|NOW reporting allows a user to view work from the standard that is of a similar standard to their own, as well as work that is of a quality that is a little higher and a little lower.

Despite being only a few weeks since our last Newsletter, we have plenty to share in this update, the highlight being the extension of RM Compare | ⚡NOW onto non-mobile devices.
When you build a mobile experience for comparative judgement, the temptation is to start with the desktop application and ask: how can we fit everything onto a smaller screen? With RM Compare |⚡NOW, we asked a different question: what does someone need to make a useful comparison, right now?
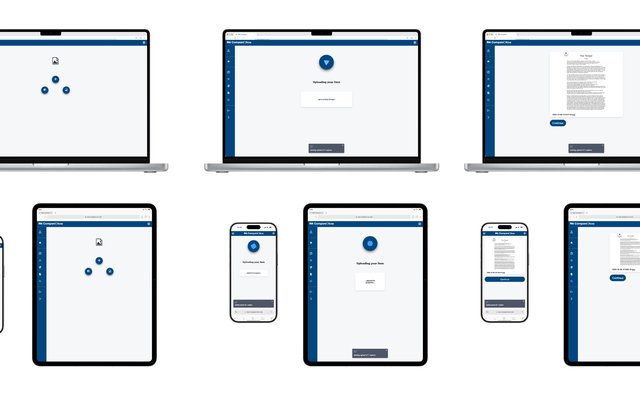
Hot on the heels of the 'mobile first' release of RM Compare | ⚡NOW. we are pleased to make it accessible on any* device.
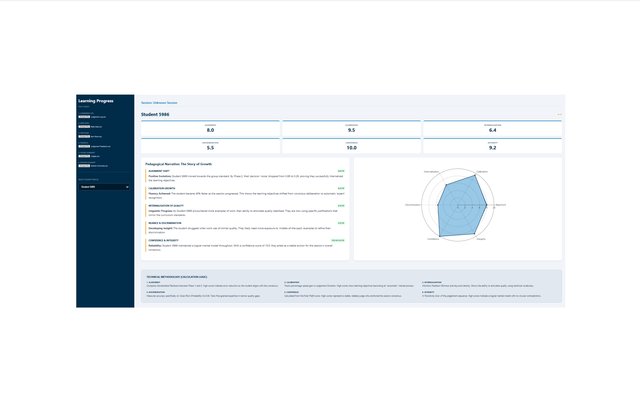
At RM Compare, we believe that the true value of Comparative Judgement isn't just found in the final rank order (the product), but in the cognitive journey students take to get there (the process). Today, we are excited to share an experimental piece of work: the Learning Progress Dashboard.
The government’s post‑16 Level 3 and below reforms are no longer abstract policy; they are now a concrete redesign of the 16–19 landscape. A Levels, T Levels, new V Levels and two reformed Level 2 pathways will replace a crowded field of overlapping qualifications. In that world, assessment quality, standards and progression evidence stop being technical details and become existential questions for awarding organisations and providers.

This post sketches what a fair, defensible appeals process can look like when RM Compare sits at the heart of grading. The short version is that appeals do not disappear; they become more transparent and more evidence‑rich, because every judgement and every decision point is logged.

When ACJ is judged by rubric‑first assumptions, it will always look like a poor imitation of traditional marking: more judgements, awkward grade mapping, fewer boxes ticked. If we instead start from its own epistemology - holistic, relative, expert judgement as the primary evidence of quality - then workload becomes a design and scheduling question, not an intrinsic flaw.

On the surface, nothing at all. Bruin is a gentle, long‑backed gundog who has just trotted his way to Best in Show at Crufts, padding calmly down the famous green carpet while the NEC holds its breath. Breakers will spin and freeze their way across an Olympic floor to pounding music. Examiners sit alone with stacks of scripts and detailed mark schemes. Three very different worlds, three very different kinds of performance.
In Part 1 of this series, we asked who gets to define “learning” in an AI world and argued for a human‑grounded validity layer alongside AI‑native analytics. That conversation becomes very concrete when you look at one small, easy‑to‑miss element in OpenAI’s Learning Outcomes Measurement Suite diagram
OpenAI’s new “Learning Outcomes Measurement Suite” is more than a product announcement; it is a bid to define how AI‑mediated learning will be measured – and, by implication, what will count as learning in the years ahead
For years, RM Compare has helped teachers, exam boards, universities and recruiters turn thousands of “which is better?” decisions into fair, reliable rankings of complex work. What began as a powerful way to compare pieces of work has now grown into something bigger: a complete ecosystem for creating, managing, and using gold‑standard judgements at scale. Today we’re introducing RM Compare | Live, Studio, Hub – three modules that work together as a continuous flywheel.
For this edition we have produced a couple of series focusing on two critical considerations in the world of assessment, and education more generally. The 'AI World' is moving fast and finding time for necessary thinking and consideration has never been more important.